LogProgress, newest first.
Wins, failures and baselines. RSS feed.
2026-10-23
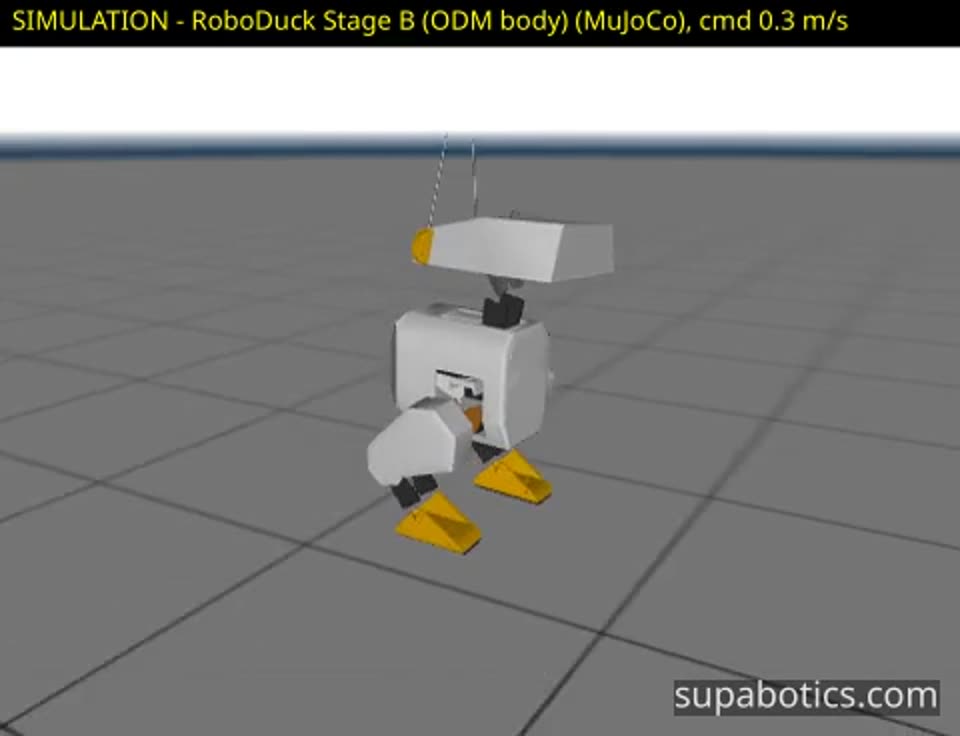 SIMULATION
RoboDuckSIMULATION
RoboDuck walks in simulation
RoboDuck's walking policy, trained with reinforcement learning in MuJoCo. At a 0.1 m/s command with a 0.12 floor it tracked 101.5% ± 2.1 of the target across 3 seeds × 10 runs with zero falls. Simulation only; no hardware yet.
Original post →
2026-10-23
LaundryBotoffline
LaundryBot: pooling four towel datasets didn't help (yet)
We pooled four public two-arm towel-folding datasets and trained the same small policy on the pooled data and on one dataset alone. Pooled 10-step action error: 0.1442. Single dataset: 0.1321. Hold-position baseline: 0.1744. Next we test per-dataset normalization.
These are offline metrics on recorded data, not robot success rates. No hardware yet.